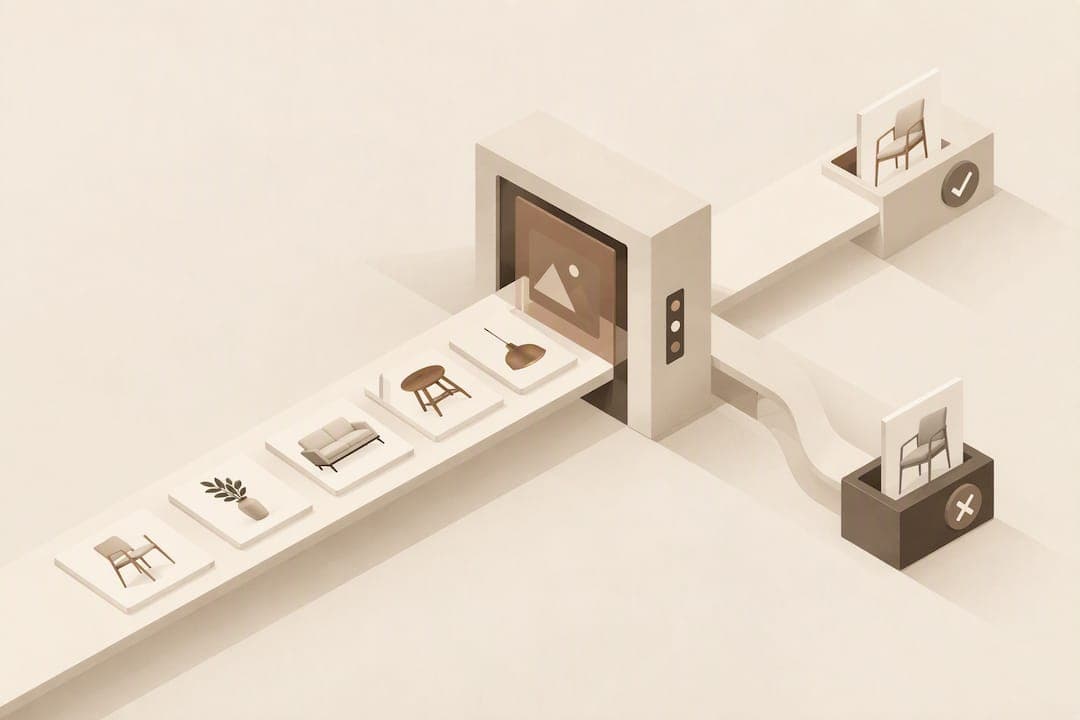
Use a hybrid pipeline: fast automated screening to filter obvious harms, plus a human-in-the-loop queue for edge cases. Every upload should resolve to one of three outcomes: allow, send to review, or block. Build measurement and feedback loops in from day one, because a moderation system you cannot measure is one you cannot trust.
TL;DR:
- Start with a managed moderation API; host your own model only when volume makes image fees exceed infrastructure costs and you need specialized categories.
- Block and report suspected sexual content involving minors and nonconsensual intimate images immediately; send violence and copyright questions to reviewers, since context can change decisions.
- Run authoritative server checks before storing or displaying uploads; client side checks can give instant feedback, but they cannot make binding moderation decisions.
- Label a few thousand images across every category, include adversarial examples, and test threshold changes as A/B experiments; monitor precision, recall, review rates, and appeals.
- For private room preview tools, screen uploads synchronously for format and basic content, reserving deeper review for flagged or sampled images rather than every photo.
Table of Contents
- Why image moderation needs its own approach
- Automated moderation methods: APIs, models and detection techniques
- Designing human review: triage, queues and reviewer tooling
- Where to place moderation checks in your upload pipeline
- Defining moderation categories and mapping severity to action
- Measuring moderation performance and setting KPIs
- Choosing integration options and tools for a pilot
- What platform signals say about reducing moderation burden
- Handling the range of formats and sizes shoppers actually upload
- Giving users real-time feedback during upload
- Integrating moderation with product-page widget functionality
- Managing uploaded images for processing speed and storage costs
- Handling borderline and ambiguous images
- A pragmatic 90-day starting plan
- A lower-friction alternative to open photo uploads
- FAQ
- Sources
Why image moderation needs its own approach
Text moderation has had years to mature around keyword lists and language models. Images are harder: a kitchen knife on a chopping board and a kitchen knife used as a threat look nearly identical to a classifier without context, and the same picture can be entirely benign in one setting and a policy violation in another. Synthetic and AI-generated images add another layer, since provenance and watermark signals are still developing and cannot be relied on alone, as the NIST guidance on synthetic content makes clear.
A platform accepting user uploads should set goals before picking any tool:
- Protect users from exposure to graphic, sexual or exploitative imagery.
- Protect the brand from being associated with harmful or illegal content.
- Reduce legal exposure in every jurisdiction the platform serves.
- Keep the upload experience fast and frustration-free for legitimate users.
Those four goals pull in different directions. Tighter filters cut legal risk but slow down honest users; looser filters protect speed but raise brand and legal exposure. The rest of this piece is about finding a workable balance.
Automated moderation methods: APIs, models and detection techniques
Automated screening is the first line of defence, and for most teams it should start with a managed API rather than a custom model. Managed services give you broad coverage across nudity, violence and weapons out of the box, with no training data required. Amazon Shopping's move to Rekognition for reviewer-submitted images is a useful reference point: migrating from in-house NSFW models to a managed moderation API improved detection accuracy and let the team automate a significantly larger volume of images annually that would previously have needed a human look.
Self-hosted models become worth considering once volume is high enough that per-image API costs outweigh infrastructure costs, or when you need domain-specific categories a general API will not cover well, such as counterfeit furniture logos or brand-specific weapon types.
Key techniques to combine:
- Multi-model ensembles: separate models or scoring axes for nudity, violence, weapons and text embedded in images, since a single blended score hides which axis triggered a flag.
- Hashing against known banned images: perceptual hashing catches previously identified illegal or policy-violating files even when resized or recompressed.
- Metadata and EXIF checks: useful for provenance, but metadata is routinely stripped by browsers and apps before upload, so treat it as a weak, optional signal rather than a control.
- Synthetic content and provenance detection: watermark and provenance signals help flag AI-generated images, though NIST is explicit that these technical tools do not guarantee safety on their own and need human validation for nuanced cases.
Pro Tip: Score each risk axis separately and log the raw scores, not just the final allow/block decision. You will need that granularity later to retune thresholds without rerunning every image.
Designing human review: triage, queues and reviewer tooling
Automated scores should route images into three lanes: clear allow (low scores across all axes), clear block (high confidence on a severe category) and a review queue for anything in between or anything flagged on an ambiguous axis. Getting the thresholds right matters more than getting the model right, since most moderation failures are threshold failures, not model failures.
A workable human review workflow looks like this:
- Triage: route by score band and category, with the highest-risk categories (suspected illegal content, suspected minors) escalated immediately rather than queued normally.
- Structured decision UI: reviewers choose from a fixed set of labels and reasons, never free text alone, so decisions stay comparable across reviewers and over time.
- Quality control: sample a percentage of reviewer decisions for a second opinion and track inter-rater agreement to catch drift or inconsistent judgement calls.
- Feedback into the model: every override, where a reviewer disagrees with the automated score, gets logged and fed back into threshold tuning or retraining, because that disagreement is exactly the data you need to close the gap between the model and your actual policy. This human-in-the-loop logging is what lets a moderation system improve on its own specific edge cases rather than staying generic.
Amazon Ads' approach to UGC environments illustrates this well: rather than judging a whole property as safe or unsafe, it evaluates content at the section level, combining automated detection with ongoing human evaluation so that one risky section does not take an entire otherwise-safe property out of ad eligibility.
Pro Tip: Give reviewers a maximum queue depth target, not just a throughput target. A growing backlog quietly increases the time a harmful image stays live, which matters more than average handling time.
Where to place moderation checks in your upload pipeline
The placement of checks shapes both user experience and risk exposure. A sensible pattern layers three stages:
- Client-side quick checks (file type, size, basic nudity heuristics) give instant feedback before upload even completes, improving perceived speed, but these are never authoritative since they run on a device you do not control.
- Server-side synchronous checks run on arrival and make the allow/block call for high-severity categories before the image is ever stored or shown, which is the only safe place for a binding decision.
- Asynchronous review handles the review-queue lane: the image can be provisionally hidden or watermarked as "pending" while a human decision completes in the background, often via a cloud function or staging queue that notifies the uploader once resolved.
Edge enforcement, blocking at the CDN or gateway layer, works well once a hash or signature is confirmed bad, since it stops redistribution without re-running the full pipeline each time.
Storage decisions tie directly into privacy obligations. Images held for review purposes should have a defined retention window and a documented deletion path, since users in many jurisdictions can request deletion of content they uploaded. A structured deletion process for user-submitted photos is a useful model for building that path: a clear request intake, a verification step, and a confirmed removal from both live storage and any review archive.
Defining moderation categories and mapping severity to action
Clear category definitions stop reviewers and models from disagreeing about what they are even looking for. At minimum, define:
- NSFW/nudity: explicit sexual content or nudity outside clearly permitted contexts (such as medical or artistic uploads your policy explicitly carves out).
- Sexual content involving minors: zero-tolerance category, always immediate block and report, never routed to standard review.
- Graphic violence: real or realistic depictions of serious injury, death or gore beyond what the platform's audience and purpose justify.
- Illegal goods: weapons, drugs or other regulated items shown for sale or promotion where prohibited.
- Non-consensual intimate images: intimate imagery shared without the subject's consent, always block and report regardless of severity scoring.
- Copyright infringement: uploaded images using protected material without rights, typically review rather than automatic block, since context and licence status are often unclear from the image alone.
Severity should map directly to action: zero-tolerance categories (minors, non-consensual intimate images) bypass review and go straight to block plus report; mid-severity ambiguous categories (violence, copyright) go to review; low-confidence low-severity flags can often auto-allow with logging. Legal obligations around these categories vary by jurisdiction, and the EU's Digital Services Act transparency templates are a useful reference for platforms operating in the EU, since they set out what in-scope providers must report and by when.
Measuring moderation performance and setting KPIs
A moderation system needs the same rigour as any other classifier. Precision tells you what share of flagged images were genuinely violations; recall tells you what share of actual violations your system caught; F1 balances the two when neither alone tells the full story. Low precision burns reviewer time on false positives; low recall lets real harms through.
Operational KPIs worth tracking alongside the model metrics:
- Human review rate: the percentage of uploads that land in the review queue rather than auto-resolving.
- Time-to-action: how long a flagged image stays live before a decision is made.
- Appeals rate: how often users successfully contest a block, a signal of threshold miscalibration.
- Moderator throughput and well-being: reviewing harmful content at volume has a real human cost, and AWS reports that moving to managed moderation APIs reduced both human review volume and the associated strain on reviewers.
Managed moderation APIs can meaningfully cut human review volume, as shown when Amazon migrated its in-house models to Rekognition and automated roughly one million additional images annually that had previously needed manual review.
Test before launch with a labelled test set covering every category, add adversarial samples designed to fool the model, and run threshold changes as A/B experiments rather than blanket adjustments, since a small threshold shift can swing review volume substantially.
Choosing integration options and tools for a pilot
Picking a stack means weighing four trade-offs: speed of integration, latency added to the upload flow, cost per image at your expected volume, and how much you can customise categories and thresholds. A managed API wins on the first and last of those for most teams starting out; a self-hosted model only pays off once volume and customisation needs are both high.
Before committing, run through a short checklist:
- Throughput needs: estimate peak uploads per minute and confirm the chosen API or model can sustain that without queuing delays.
- Fallback paths: decide what happens if the moderation service is slow or unavailable, since blocking all uploads during an outage is rarely the right default.
- SDKs and webhooks: confirm the vendor supports your stack natively or via webhook callbacks for the asynchronous review lane.
- Monitoring: wire up dashboards for the KPIs above before launch, not after an incident forces the issue.
A sensible pilot runs against a few thousand labelled images, tunes thresholds against that set, and staffs the review queue based on the expected review rate from testing, typically starting with one reviewer per few thousand daily uploads and adjusting once real volume and review rates are known.
What platform signals say about reducing moderation burden
Some of the moderation burden teams face comes from accepting arbitrary, unconstrained photo uploads in the first place. Our product-page widget takes a narrower approach: instead of asking shoppers to upload freeform images for open display, it composites a retailer's own furniture photo into a shopper's room photo, entirely without requiring an app download. That constrained use case, a single room photo used only to generate a private preview, carries a different risk profile to an open UGC gallery.
We rely on the product images retailers already have rather than building 3D models, which keeps the moderation surface smaller and more predictable, as we explain in our notes on choosing a visualisation approach. The 500 free previews we offer new retailers let a team test that upload and preview experience, including how photos are handled and deleted, before any production decision is made.
Handling the range of formats and sizes shoppers actually upload
Real-world uploads arrive as JPEG, PNG, HEIC from iPhones, and occasionally WebP, in resolutions ranging from a few hundred pixels to full-resolution camera files several megabytes in size. A moderation pipeline needs to normalise before it classifies: convert HEIC to a standard format early, since several moderation APIs do not accept it directly, and downscale oversized images before they reach a model, since most classifiers are trained and evaluated at modest resolutions and gain nothing from a 20-megapixel input beyond slower processing.

Set hard limits on file size and dimensions at the point of upload, with a clear client-side message when a file is rejected, rather than letting a server silently time out on an oversized file. Reject corrupted or malformed files before they reach the moderation step at all, since a classifier fed a broken file can return unpredictable results rather than a clean error.
Store a single normalised working copy for moderation and downstream processing, keeping the original only if your retention policy requires it. Adopting a consistent output format such as WebP for anything that needs to be served back to users also helps processing speed and storage costs, as outlined in guidance on WebP for ecommerce, since WebP files typically run smaller than equivalent JPEGs at the same visual quality.
Giving users real-time feedback during upload
Users tolerate a moderation delay far better when they can see what is happening. A short, honest status message, "checking your image", followed by a result within a second or two for the automated pass, keeps the experience feeling responsive even when a full decision is still pending.
For the review-queue lane, set expectations clearly rather than leaving an upload in limbo: tell the user their image is pending review and give a realistic timeframe, then notify them (in-app or by email) once a decision is made. Silence is the worst option, since it reads as a bug rather than a deliberate process.
Avoid revealing the precise reason for a block in granular detail, since that information helps bad actors learn to evade detection, but do give enough for a legitimate user to understand and correct the issue, such as "this image was flagged for violent content" rather than a generic "upload failed". Where a block is wrong, make the appeal path visible immediately rather than buried in a help centre.
This real-time layer also needs to handle the client-side quick checks from earlier in the pipeline: a file that is clearly the wrong type or far too large should fail instantly, locally, before it ever reaches a server and a review queue.
Integrating moderation with product-page widget functionality
Product-page widgets that accept a user photo, such as a "see it in your room" style tool, sit in an interesting middle ground: the uploaded image is used to generate a composited preview rather than being published for other users to see. That changes what moderation needs to catch. There is no need to screen for brand-safety concerns aimed at other viewers, since the output is typically private to the uploader, but checks against illegal or exploitative content still matter, because the image still passes through storage and processing infrastructure.
A practical integration pattern runs a lightweight automated check (format validity, basic content screening) synchronously as part of the compositing request, since the user is waiting for a result within seconds, and reserves any deeper review for a small sampled or flagged subset rather than every upload. This mirrors the broader pattern of fast automated screening plus a narrower human-in-the-loop lane, just scaled to a lower-risk use case.
Retailers evaluating this kind of widget should ask the vendor directly how uploaded room photos are screened, stored and deleted, since that detail rarely appears on a marketing page but matters for data protection compliance. Our own deletion process for user-submitted room photos is one example of making that workflow explicit rather than leaving it implicit.
Managing uploaded images for processing speed and storage costs
Image moderation and image storage costs rise together, so design for both from the start. Running moderation checks on a resized, compressed working copy rather than the full original cuts both processing time and the bandwidth cost of feeding images into an API, with negligible loss of classification accuracy for most categories.
Set a lifecycle policy for stored images rather than keeping everything indefinitely: automated-allow images can often move to cheaper, colder storage tiers quickly, while review-queue images need faster access for the short window a human decision takes, and blocked images should be purged on a defined schedule once any legal retention requirement is satisfied.
Batch non-urgent reprocessing, such as rerunning an updated model against historical images, during off-peak hours rather than competing with live upload traffic. And track storage growth against upload volume monthly, since a slow creep in average file size (users upgrading phones, higher-resolution cameras) can quietly inflate both storage and processing bills well ahead of any deliberate volume growth.
Handling borderline and ambiguous images
Every moderation system accumulates a long tail of images that do not cleanly fit a category, artistic nudity, medical imagery, violent content in a clearly fictional or educational context, or a weapon shown in a context that is plainly not threatening. These are exactly the cases automated scoring handles worst, since a model trained on clear-cut examples has little signal for context-dependent judgement calls.
The right response is a documented escalation path rather than an ad hoc one: borderline cases route to a senior or specialist reviewer rather than the general queue, and every such decision gets logged with the reasoning, not just the outcome. Over time, those logged decisions become the basis for refining category definitions and, where the volume justifies it, training data for a model that can resolve more of the ambiguous cases automatically.
Consistency matters more than speed for this category. A platform that reverses similar borderline decisions from one week to the next erodes trust with users faster than one that is simply strict. Building a small internal reference set of past borderline decisions, with the reasoning attached, gives reviewers a consistent standard to check new ambiguous cases against rather than relying on individual judgement each time.
A pragmatic 90-day starting plan
Start with a managed moderation API rather than building your own model, since it gets protection live in weeks rather than months. Add a human-in-the-loop queue from day one, even a small one, and instrument the KPIs from the measurement section before you need them in an incident review. Prioritise the categories carrying the most legal and brand risk first, and treat every reviewer override as a signal to retune thresholds rather than a one-off correction.
— Michael
A lower-friction alternative to open photo uploads
Not every retailer needs an open UGC gallery; some explore automating their ecommerce visuals using an AI product image generator to streamline content creation. Our product-page widget lets shoppers upload a single room photo that gets composited with retailer furniture images, never published or shared, which sidesteps most of the moderation burden an open gallery creates.
- No app download for shoppers, using product photos retailers may already have.
- A constrained, private preview rather than open user-generated content.
- 500 free previews to test the experience before paying.
Run it against your own product pages with our universal demo to see how it fits your catalogue.
FAQ
Where in the upload pipeline should image moderation run?
Run lightweight checks client-side for instant feedback, then an authoritative server-side synchronous check before storing or displaying the image, with ambiguous cases routed to an asynchronous human review queue. High-severity categories should always resolve synchronously rather than waiting on a review queue.
Which moderation categories should we prioritise first?
Prioritise zero-tolerance categories first: sexual content involving minors and non-consensual intimate images, since these carry the most severe legal and safety consequences. Graphic violence, illegal goods and copyright infringement typically follow as review-queue categories rather than instant blocks.
Should we build our own moderation model or use an API?
Most teams should start with a managed API, since it provides broad category coverage without training data and can be live within weeks; Amazon's migration to Rekognition improved accuracy and cut manual review volume. A self-hosted model becomes worth considering only once volume and customisation needs both justify the extra engineering.
How do appeals and reviewer disagreements get handled?
Give every blocked or flagged user a visible appeal path rather than a dead end, and route appeals to a reviewer who was not part of the original decision. Log every overturned decision, since a rising appeals rate usually signals a threshold that needs retuning rather than a one-off mistake.
Does this type of moderation apply to room-preview or try-before-you-buy photo tools?
Yes, though the risk profile is narrower since the uploaded photo typically generates a private composited preview rather than public content. A lightweight synchronous check for format validity and basic content screening is usually sufficient, with deeper review reserved for sampled or flagged cases.
Sources
- How to protect advertisers in UGC environments | Amazon Ads
- Reducing risks posed by synthetic content: an overview of technical approaches to digital content transparency | NIST
- How Amazon Shopping uses Amazon Rekognition Content Moderation to review harmful images in product reviews
- Implementing regulation laying down templates concerning transparency reporting obligations (EU Digital Services Act)